WAIC 2026 Wrap-Up | Shengshu Technology Showcases the Latest in General World Models: From Digital World Generation to Physical World Action
On July 20, the 2026 World Artificial Intelligence Conference and High-Level Meeting on Global AI Governance (WAIC 2026) concluded in Shanghai.
During the conference, scientists, industry leaders, investors, and innovative enterprise representatives from around the world gathered in Shanghai to discuss AI technology evolution, industrial deployment, and global governance.
As AI enters a new stage of development, the industry’s central question has shifted from “what can models generate” to “can models understand the world, predict the world, interact with the world, and act in the world.”
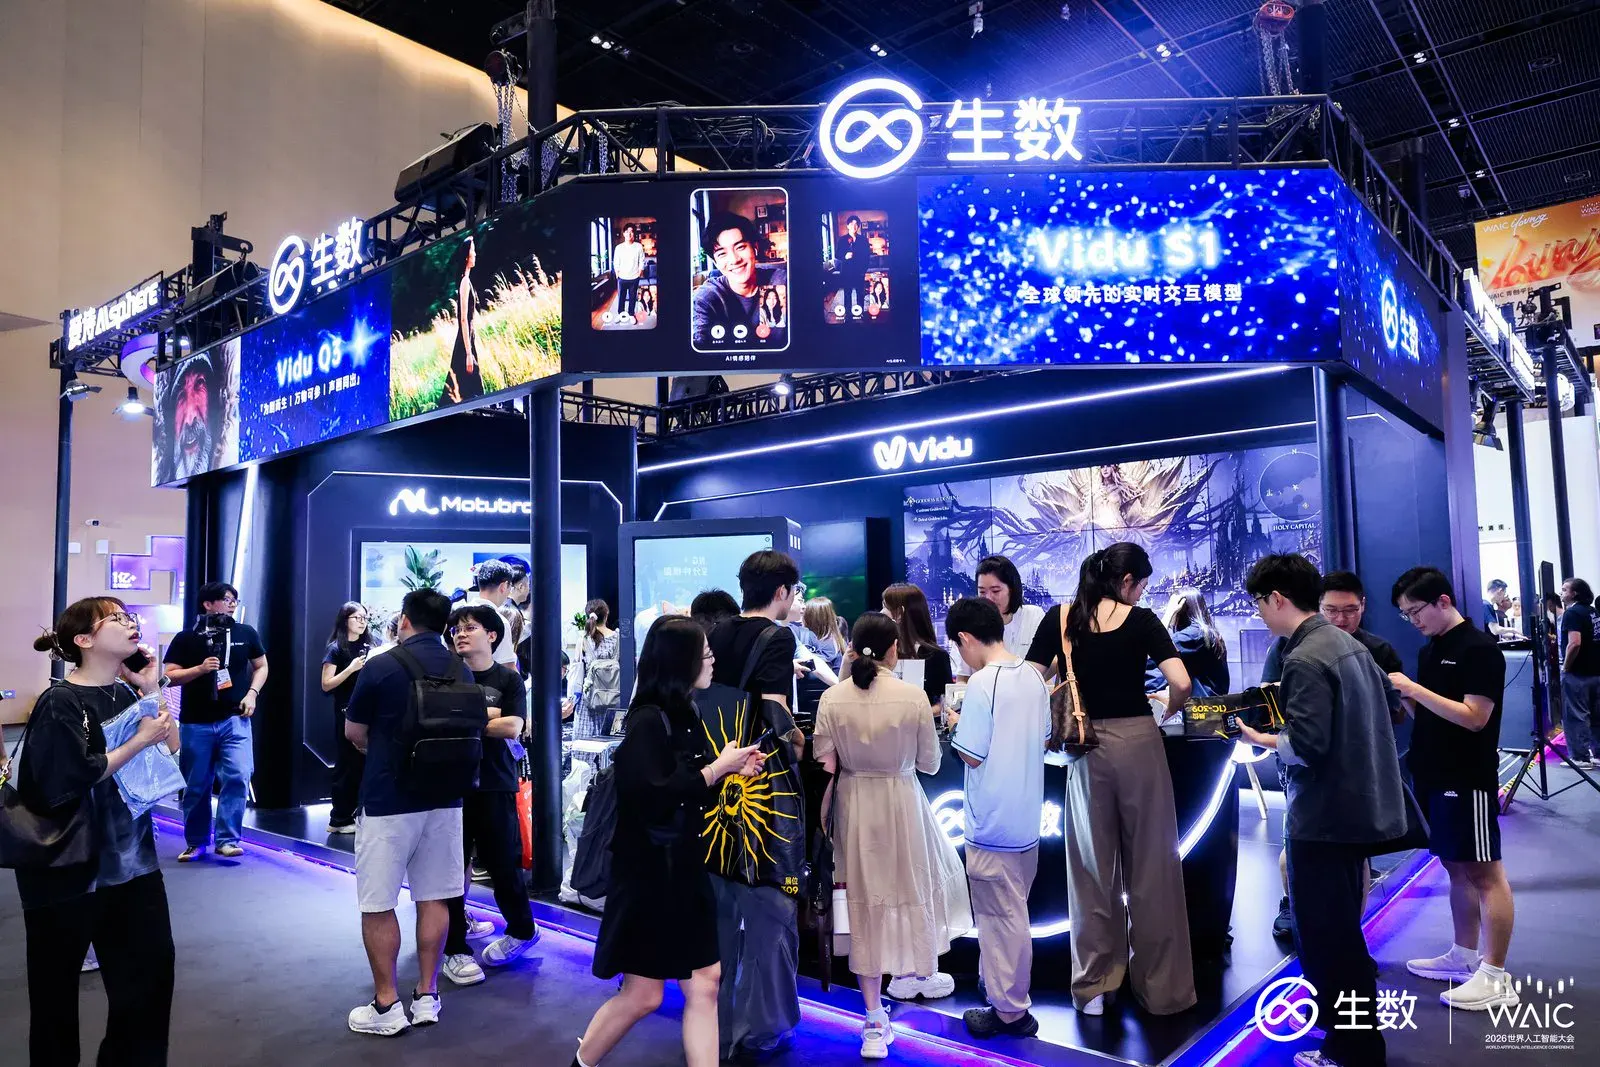
Around this trend, Shengshu Technology showcased at WAIC 2026, presenting world model breakthroughs in digital content generation, real-time interaction, and physical world action through a dedicated forum and interactive exhibition.
From the world generation model Vidu and real-time interactive model Vidu S1 to the world action model Motubrain, world models are evolving from cutting-edge concepts into experiences that can be experienced, verified, and applied in industry.
Forum Spotlight: World Models Enter the AI Film & Television Production Pipeline
On the morning of July 20, the forum “A New Paradigm for AI Film Production Driven by World Models,” co-organized by Shengshu Technology and Wondershare, was held at the Shanghai World Expo Exhibition Center. The forum connected AI infrastructure, world models, creative tools, and the film & television production chain, bringing together industry leaders from models, computing, creative platforms, film production, and data services.
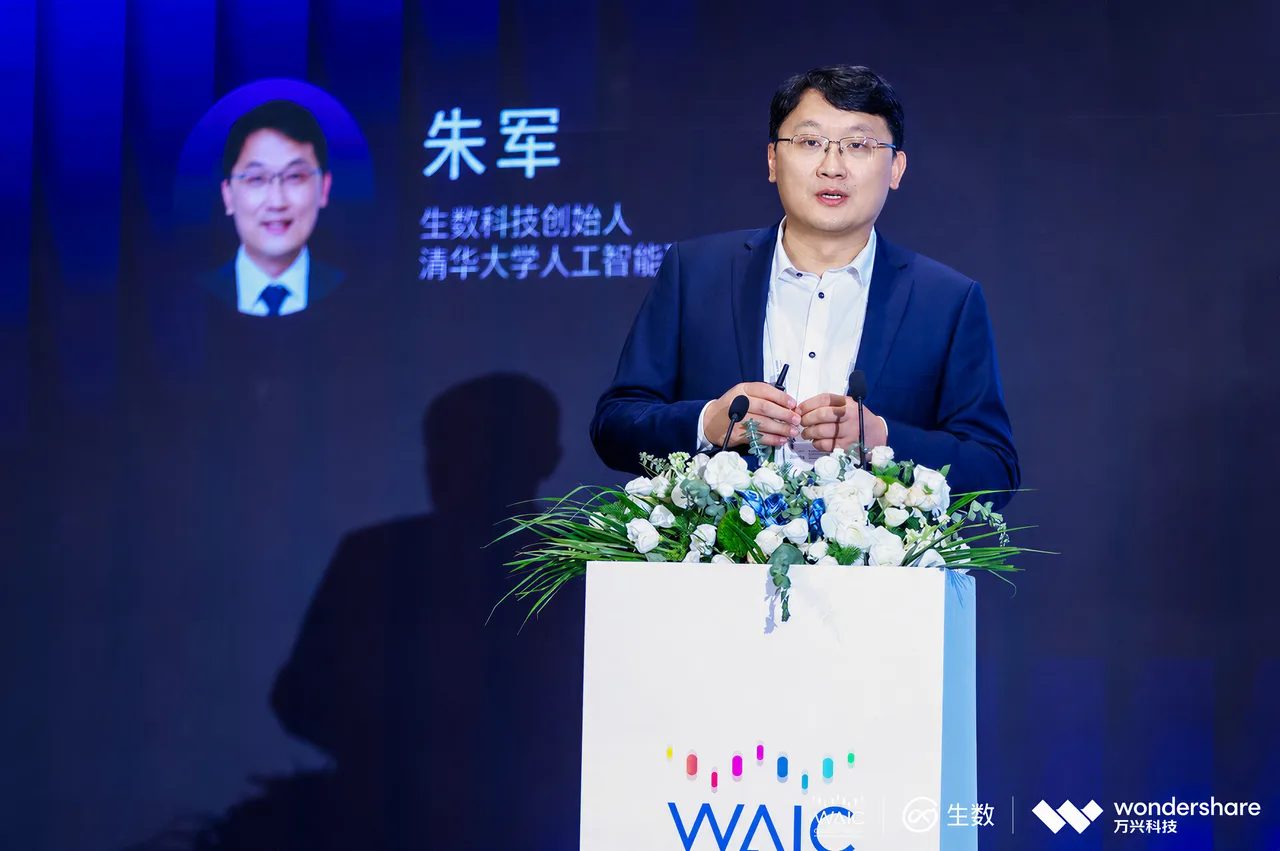
At the forum, Shengshu founder and Deputy Director of Tsinghua University’s Institute for AI, Zhu Jun, delivered a keynote titled “General World Models: New Infrastructure Bridging the Digital and Physical Worlds,” sharing the technology evolution, core capabilities, and industrial applications of general world models.
Zhu Jun stated that AI is moving from understanding and generating digital content toward modeling, reasoning about, predicting, and acting upon the laws of the world. World models are not an upgrade of video models or an extension of language models, but a new paradigm driving AI from “generating content” toward “understanding the world, reasoning about the world, and interacting with the world in real time.”
Wondershare founder and chairman Wu Taibing proposed the core industry thesis of “production paradigm reconstruction” for AI film & television, emphasizing that AI is not merely an efficiency tool for the film industry, but is fundamentally restructuring the underlying logic of industry operations. The film & television industry stands at a critical inflection point of a fourth technological leap, and AI film & television represents a brand-new digital content track with hundreds-of-billions-level growth potential.
Liu Weiguang, Senior Vice President of Alibaba Cloud Intelligence Group and President of the Public Cloud Business Unit, stated that world models are launching a new round of productivity revolution, challenging computing infrastructure, training-inference integration, data and engineering capabilities. Alibaba Cloud provides full-stack support from data, computing, training, and inference to agent deployment and globalization, fully prepared for world model iteration.
Roundtable: AI Film & Television Enters the Industrial Deep Water
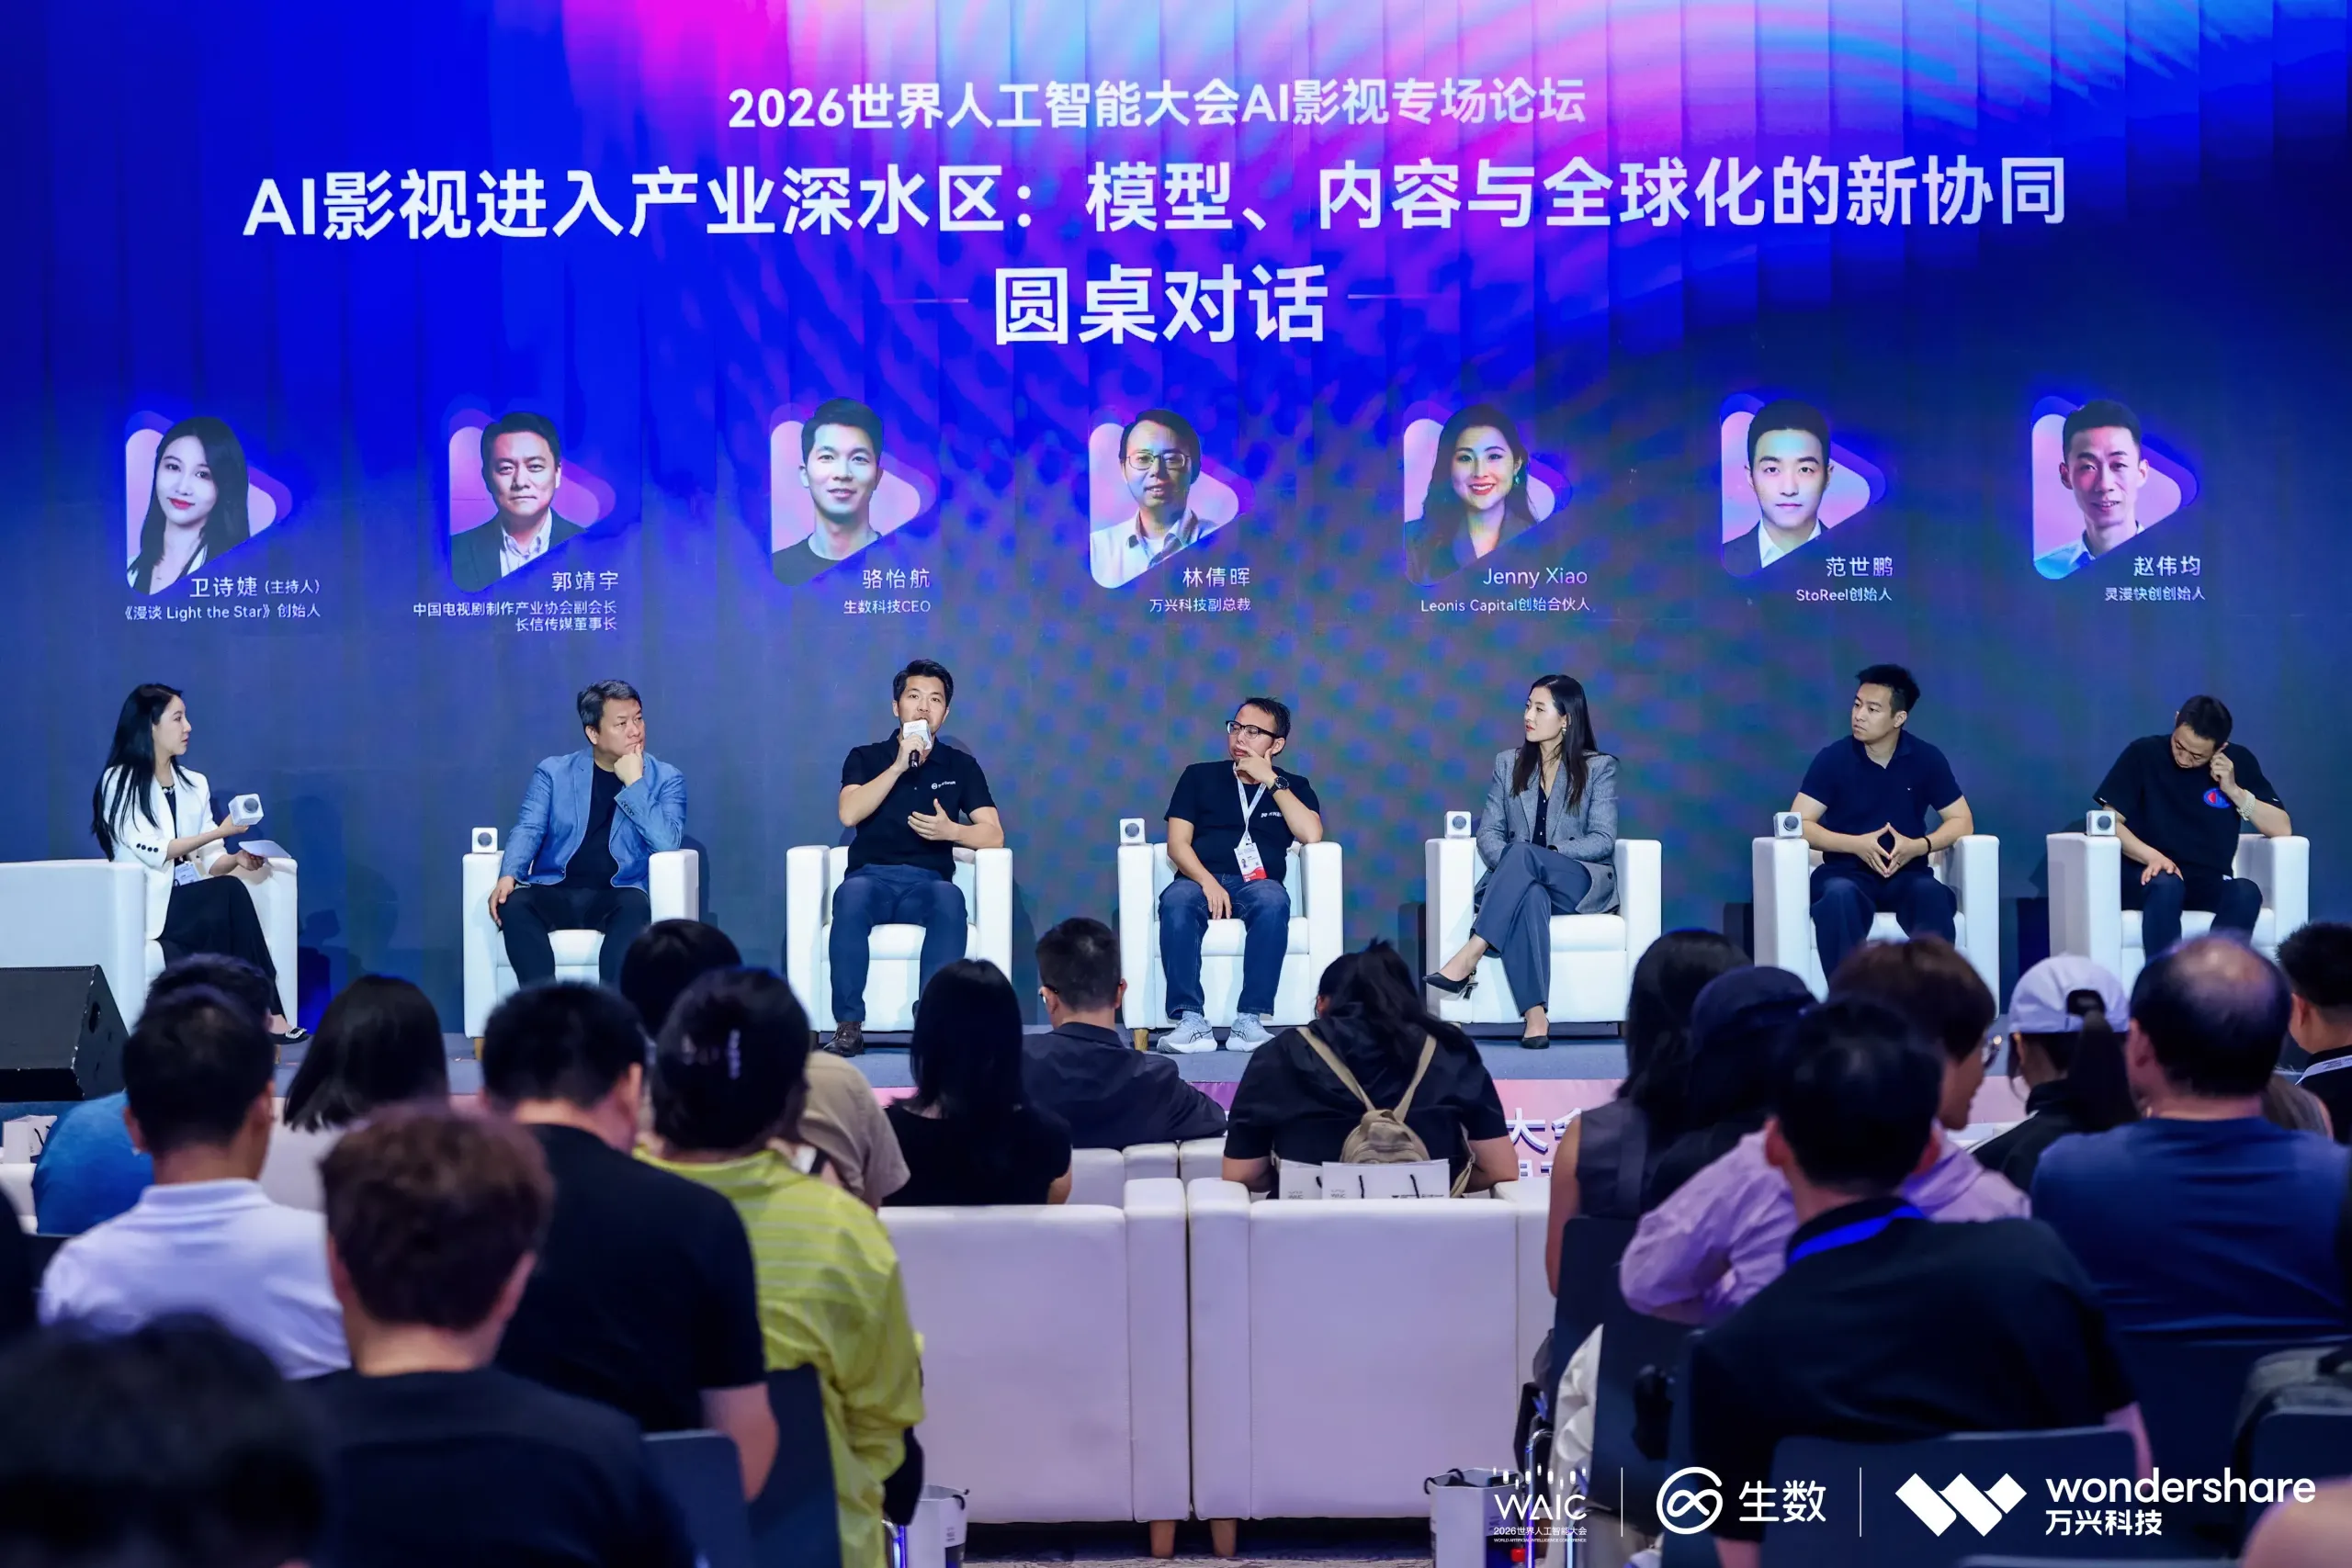
In the roundtable session, five key industry operators from technology, tools, capital, content, and global expansion tracks gathered to discuss “AI Film & Television Enters the Industrial Deep Water: New Coordination of Models, Content, and Globalization,” producing actionable and forward-looking consensus for high-quality industry development.
Luo Yihang believes the most important value of the model layer is to provide creators with greater freedom, continuously improving generation speed, efficiency, scenario adaptability, and success rates, allowing creative teams to invest more time in IP, scripts, characters, and content refinement. Currently, China has formed structural advantages in video models, creative tools, content ecosystems, and cultural IP. China’s AI film & television globalization encompasses not only content export but also serving global local creators with model capabilities. As he said: “Shengshu is committed to making models better, so creative teams can freely immerse themselves in creation, and more stories can come to life.”
At the event, Shengshu Technology and Wondershare jointly launched the “Wanju Global Alliance,” completing the signing ceremony with founding alliance partners to build a new AI global ecosystem. The alliance will adopt a “technology + content + creation + distribution + investment” full-chain collaborative model to drive the规模化 export of the AI film & television industry.
Founding alliance partners cover the full industry chain: the technology layer, with Shengshu Technology providing foundation model capabilities as the AI productivity backbone; the content layer, with leading content organizations like Changxin Media linking global IP resources; the creation layer, connecting global creators through partners like Lingman Kuaichuang; the distribution layer, with platforms like StoReel and Donglin Film enabling content export and global monetization; and the investment layer, with industrial capital like Zhejiang Cultural Investment’s Zhirong Wuxian exploring innovative “capital + computing” incubation models.
Exhibition Highlights: From Generating the Digital World to Acting in the Physical World
Beyond the forum, Shengshu Technology’s general world model technologies and products were also showcased at the WAIC exhibition. With the general world model as its foundation, Shengshu continues to build bridges connecting the digital and physical worlds.
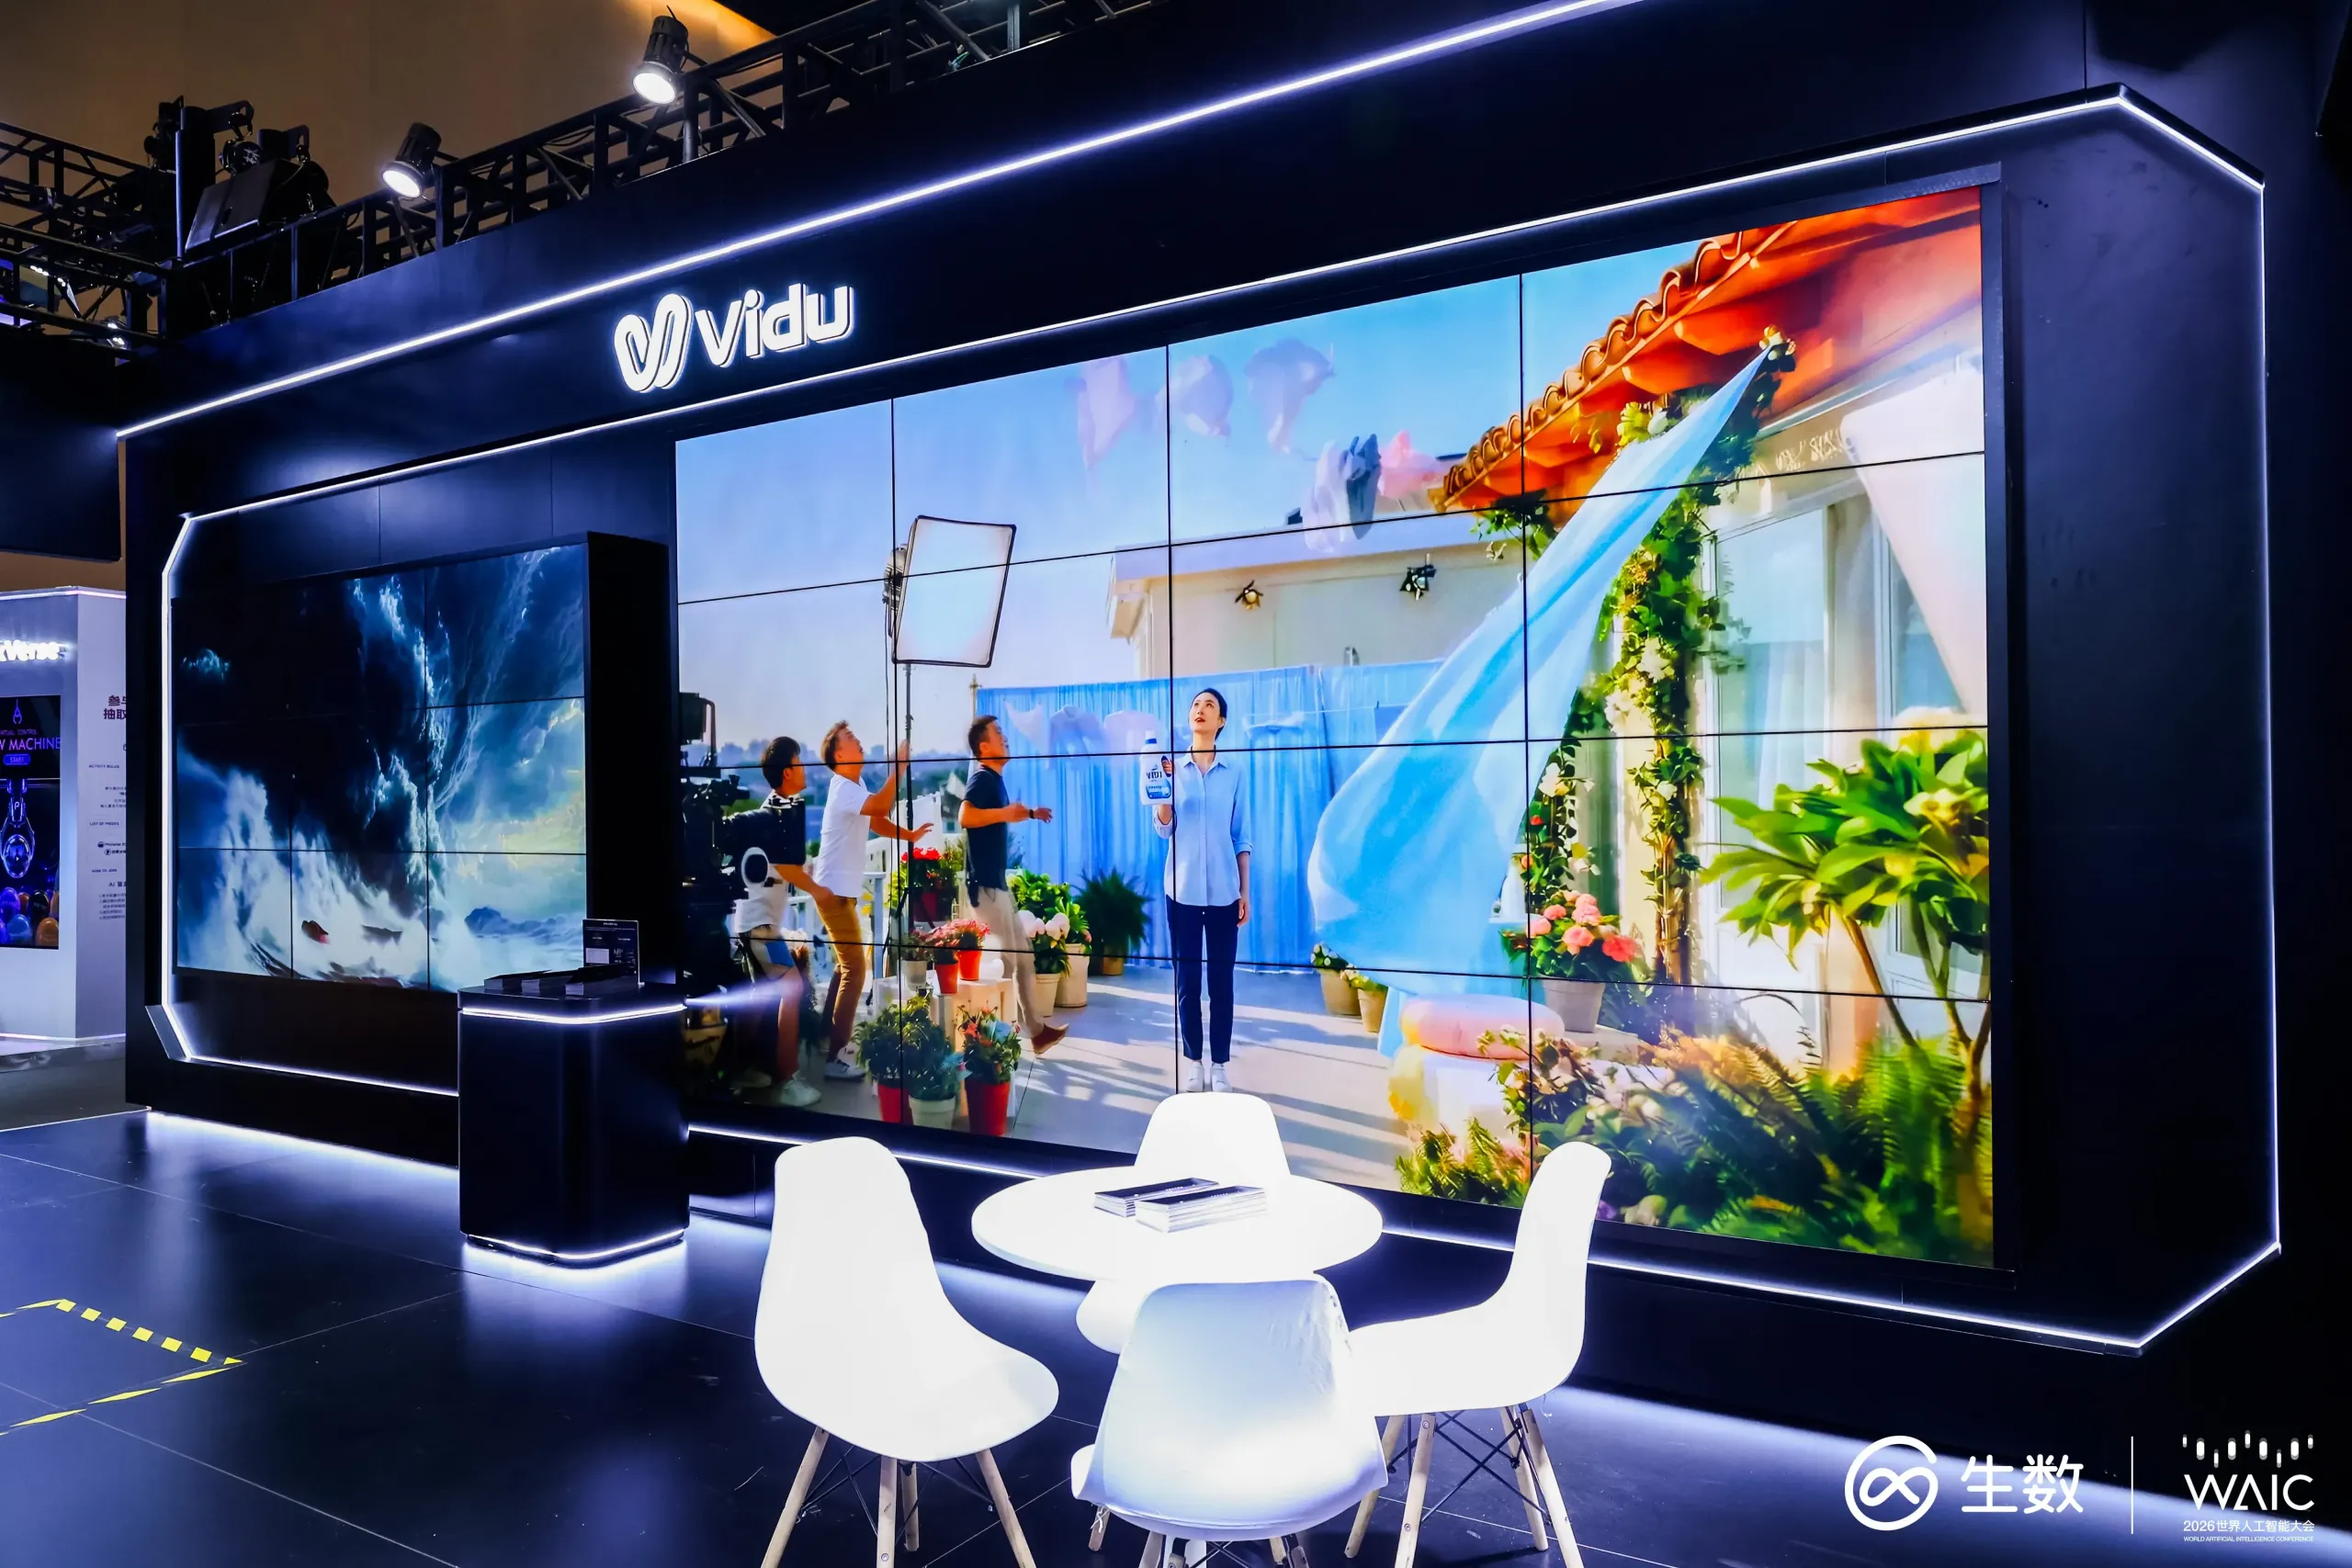
In the digital world, Vidu supports text-to-video, image-to-video, reference-to-video, and other creation methods, continuously improving content generation consistency, physical plausibility, and interactivity; Vidu S1 further advances video generation from offline content to real-time interaction.
In the physical world, the world action model Motubrain uses a single universal brain to drive multiple robots to understand, predict, and act in the world, pushing the general world model from “visual reasoning” toward “physical decision-making.”
At the exhibition, attendees experienced world model applications in content production, real-time interaction, and embodied intelligence through Vidu Q3, Vidu S1, and Motubrain demonstrations.
World Generation Model Vidu
As Shengshu’s world generation model for the digital world, Vidu leverages the foundation world model’s understanding and reconstruction of people, objects, scenes, motion, and audiovisual information to provide multimodal content generation capabilities for creators and enterprises.
Vidu supports text-to-video, image-to-video, reference-to-video, and other creation methods, continuously improving subject and scene consistency, motion performance, physical plausibility, camera control, and content interactivity, helping creators complete high-fidelity content creation more efficiently.
Rather than generating single clips, Vidu further explores the modeling and reasoning of character relationships, spatial structures, dynamic changes, and physical laws behind content, driving the model from “generating digital content” toward “understanding world patterns and constructing dynamic digital worlds.”
Currently, Vidu has formed a product and service matrix covering SaaS, MaaS API, and Agent formats, continuously serving advertising, short dramas, animated series, film & television, e-commerce, and other industries, pushing AI video from creative showcases into scaled content production workflows.
Real-Time Interactive Model Vidu S1
If traditional video generation addresses “generating a piece of content,” Vidu S1 further explores “generating a digital character that can respond in real time and interact continuously.”
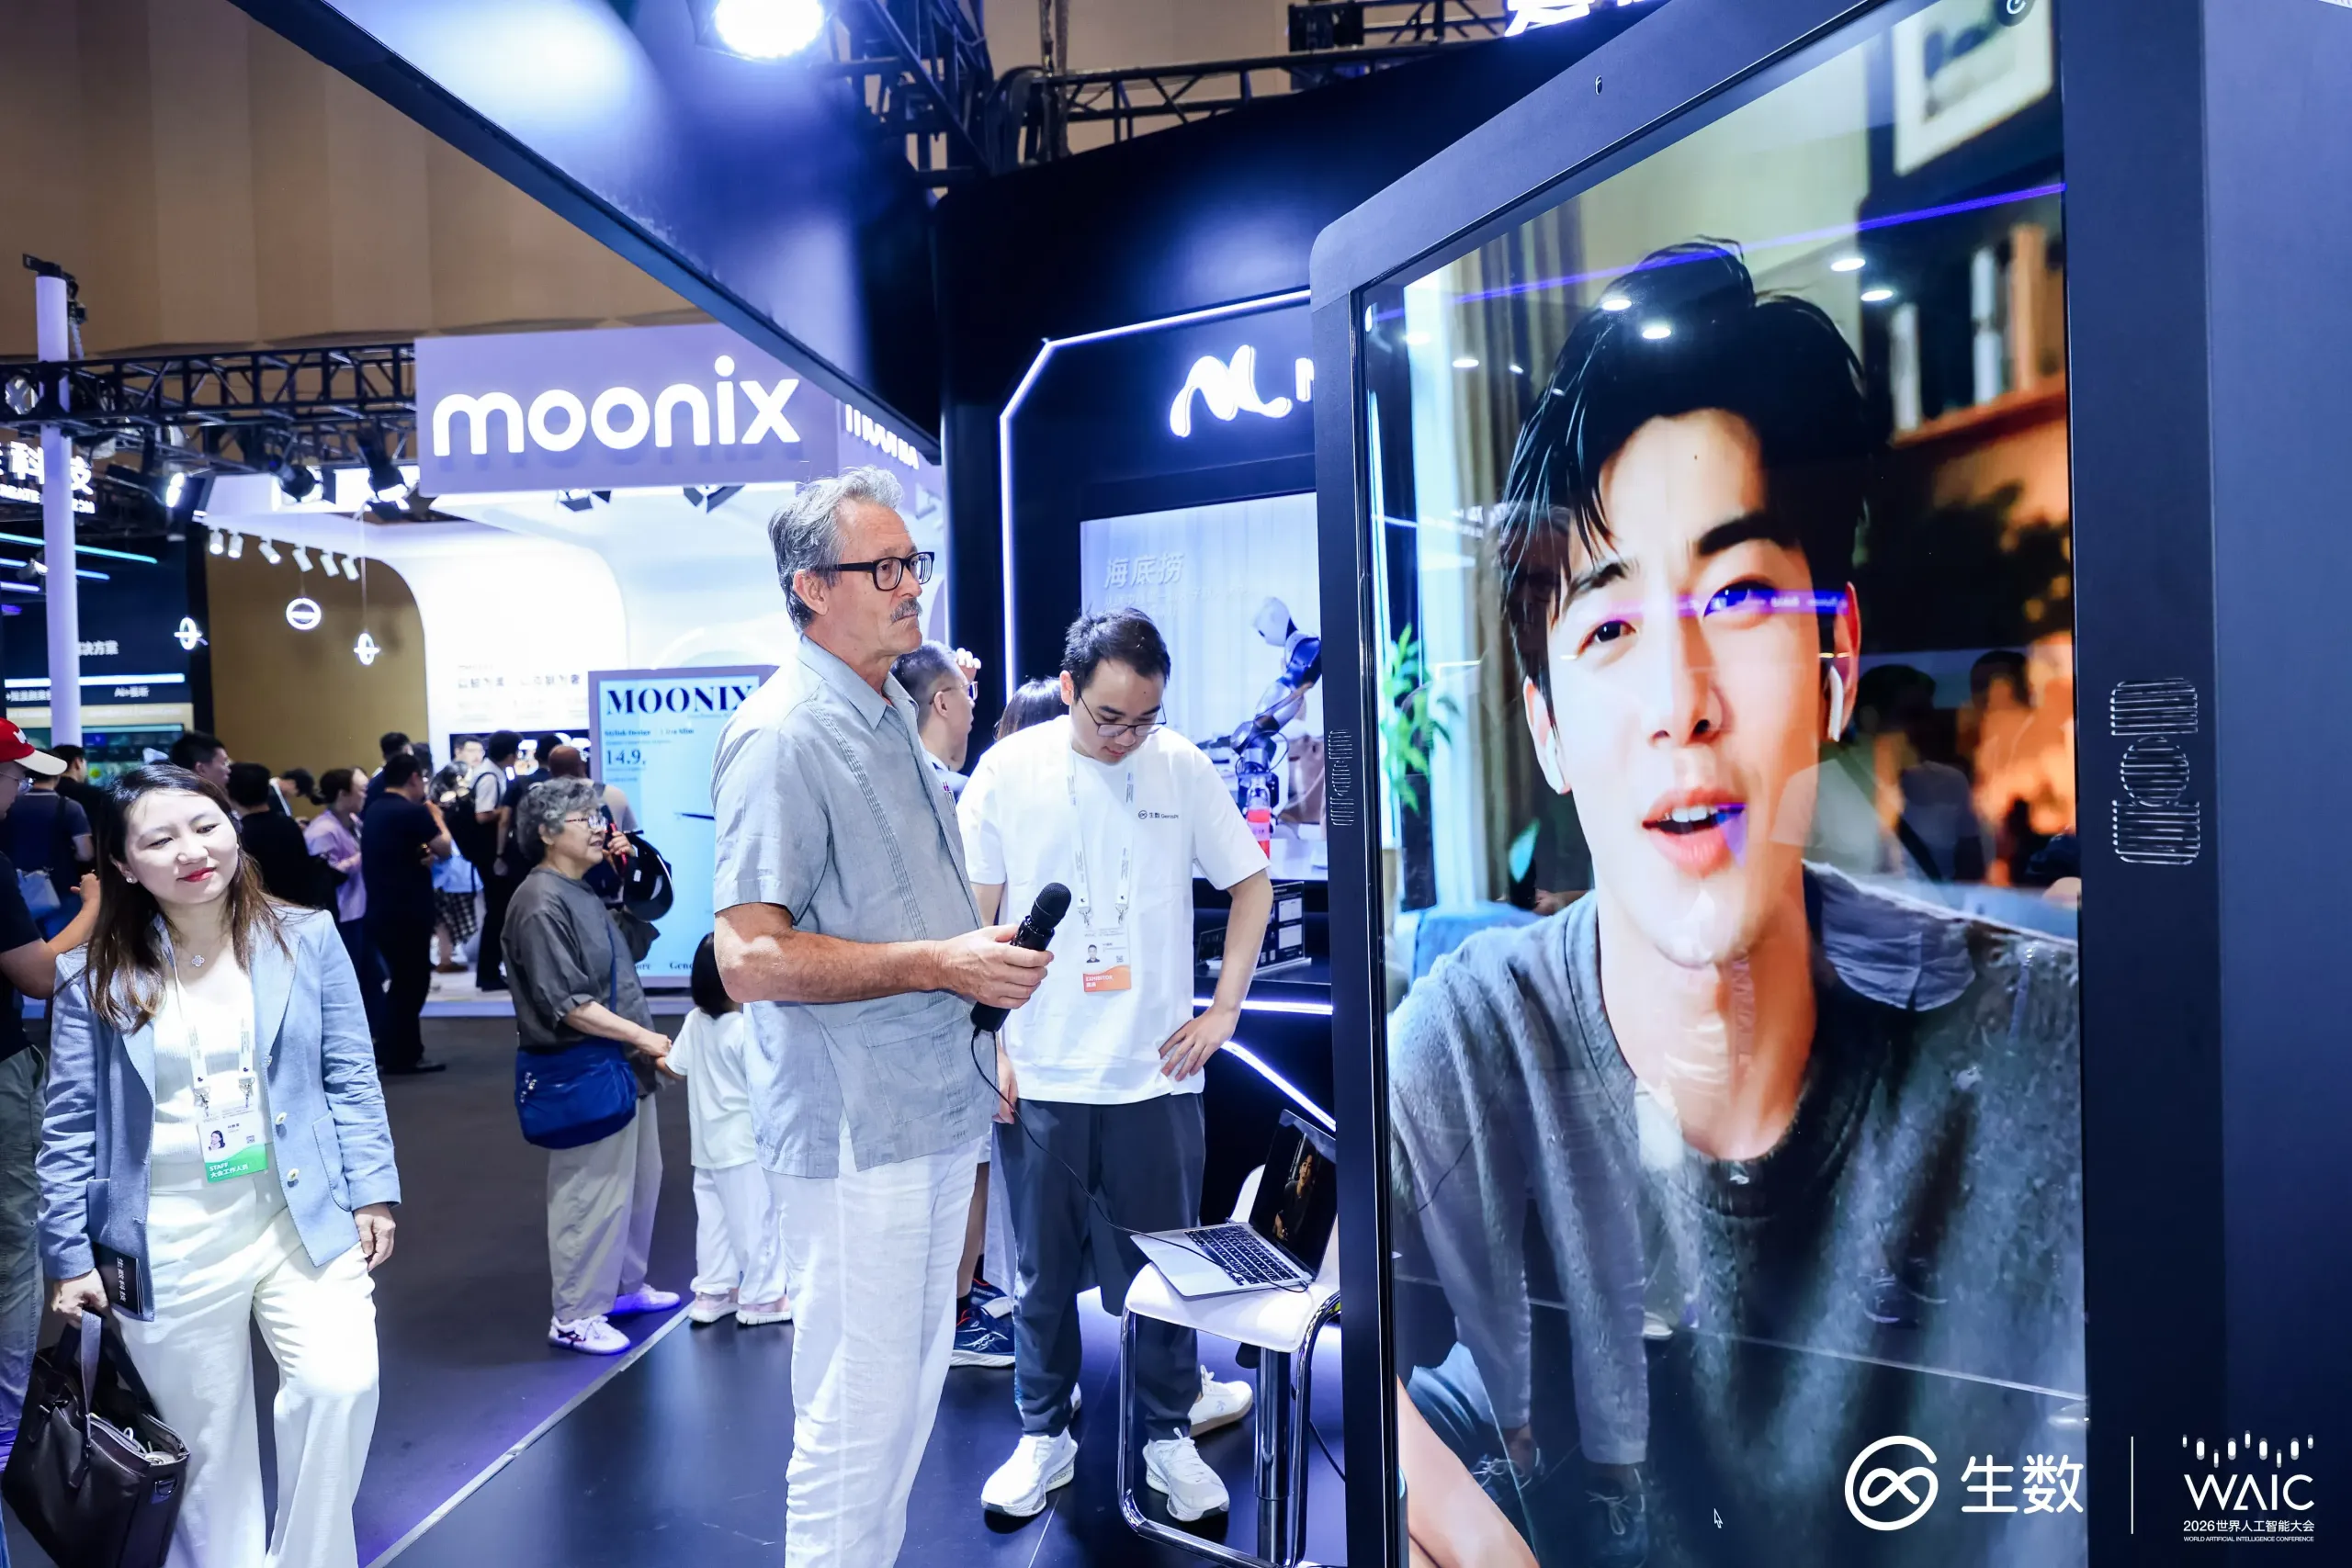
At the exhibition, users could quickly create dedicated interactive characters based on any initial image — real people, anime characters, pets — with personalized voice, and interact with the character in real time through voice.
Vidu S1 can combine voice semantics, emotions, dialogue context, and current visuals to generate character lip-sync, expressions, eye movements, gestures, body posture, and subsequent actions in real time — no longer limited to simple lip-sync or preset actions.
The model supports real-time video calls and unlimited-duration continuous interaction, achieving 540P, 25FPS video call output, with up to 42FPS support, balancing generation quality, response speed, and interaction continuity.
From generating a fixed video to generating a digital character that can respond in real time and interact continuously, Vidu S1 brings video generation into a new real-time, continuous, interactive stage, providing new technical foundations for AI emotional companionship, virtual idols, interactive live-streaming, game NPCs, brand digital humans, intelligent customer service, online education, and XR scenarios.
World Action Model Motubrain
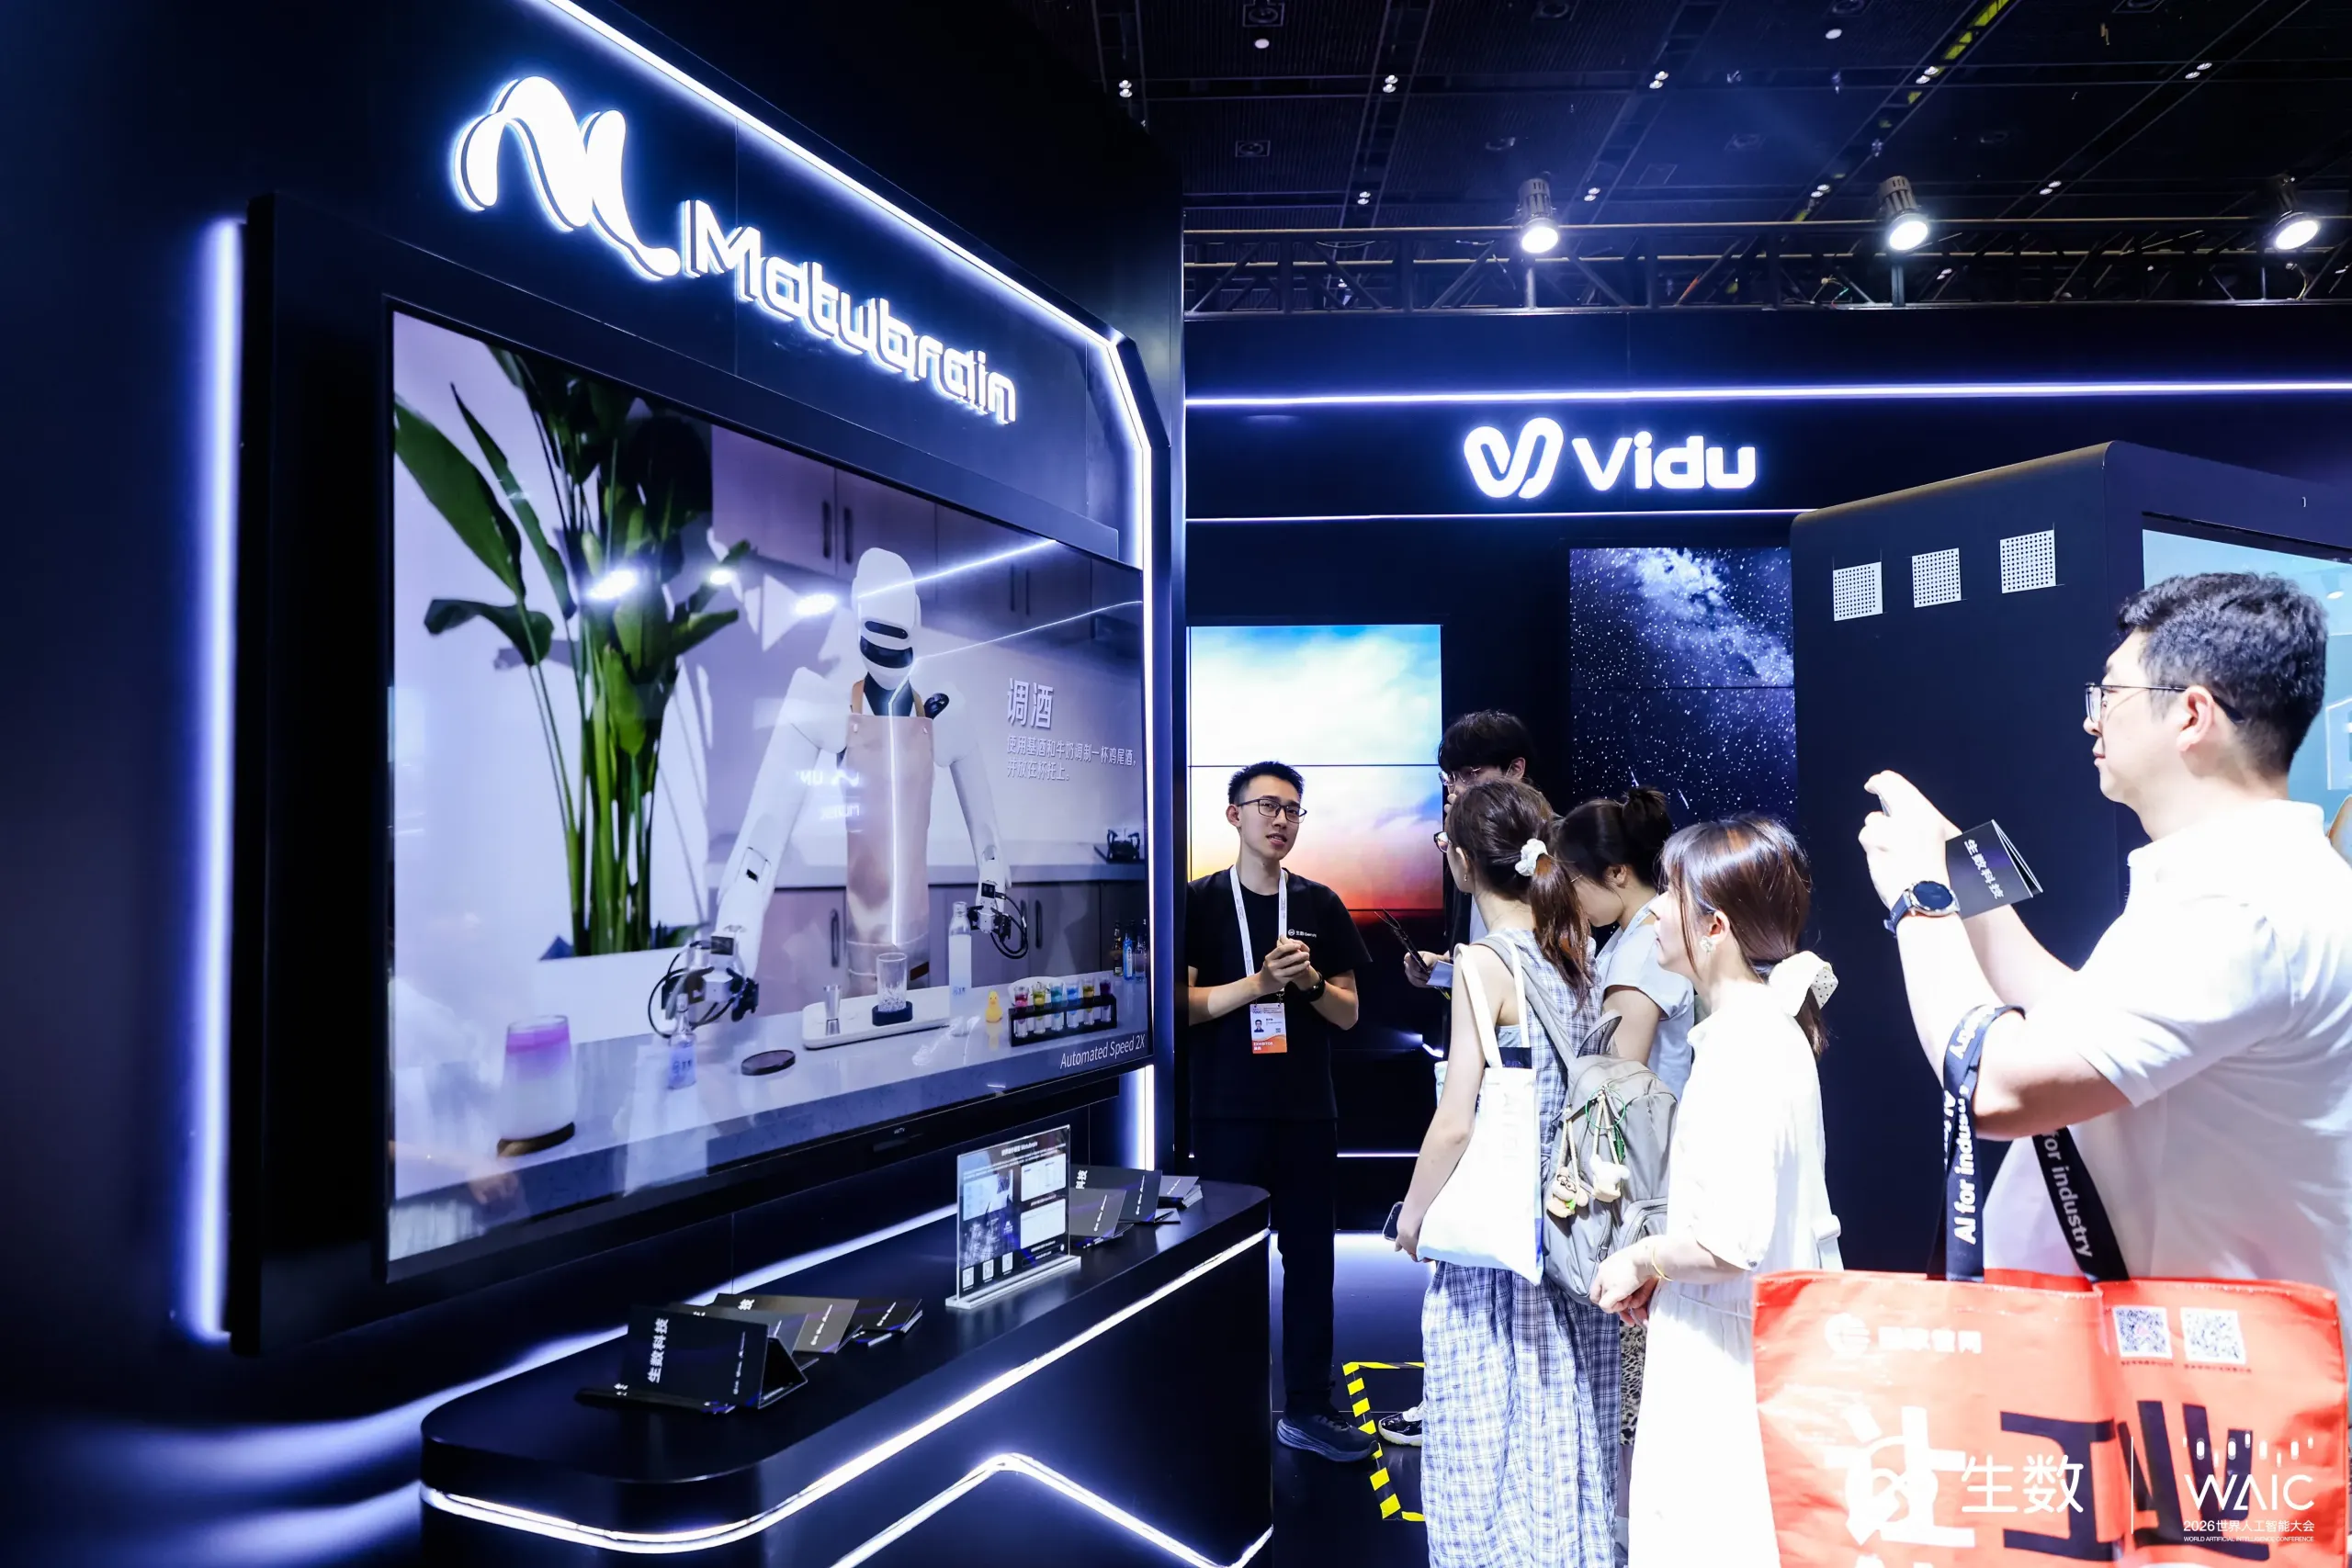
As Shengshu’s evolutionary core connecting the digital and physical worlds, the world action model Motubrain serves as a universal brain for embodied intelligent robots, driving multiple robots to understand, predict, and act in the world with a single general brain.
Motubrain adopts the Mixture-of-Transformer (MoT) architecture, integrating environmental understanding, world state prediction, and action trajectory generation into a unified model framework, reducing information fragmentation and error accumulation from multi-model cascading, enabling understanding, prediction, and action to collaborate around the same task objective.
By learning shared world knowledge across different robot embodiments, tasks, and scenarios, Motubrain has multi-embodiment adaptation, multi-task generalization, and long-horizon task execution capabilities, driving robots of different forms to more stably complete complex tasks in home, industrial, commercial, and other real-world scenarios.
In multi-task scenarios, Motubrain maintains stable performance and improves multi-task generalization through shared world knowledge; in multi-embodiment scenarios, one model adapts to multiple robots, exploring alternatives to the “one robot, one model” paradigm; in long-horizon tasks, the model directly learns complete task chains without upper-level planning, task decomposition, or multi-model stitching; in dynamic environments, the model understands and predicts environmental changes, continuously judging, adjusting, and acting accordingly.
In the RoboTwin 2.0 benchmarks, Motubrain achieved 95.8 and 96.1 in Clean and Randomized scenarios respectively, ranking first in both; in the WorldArena benchmarks, it ranked first overall with an EWM Score of 63.77, leading in multiple key dimensions including motion quality and motion fluency.
From understanding the world and predicting the world to acting in the world, Motubrain is driving embodied intelligence from point capabilities to general capabilities, from demonstration to real application.
From Model Innovation to the Industrial Scene
From Vidu to Vidu S1 to Motubrain, Shengshu Technology presented at this WAIC a clear technology and product pathway from digital world generation to physical world action.
General world models represent not only stronger content generation capabilities, but also a new type of universal intelligent foundation that can understand environments, model patterns, predict changes, and take action.
Currently, AI is restructuring content production, software tools, industrial processes, and intelligent terminals, and world models are moving from frontier research into experiences, products, and applications that can be experienced, verified, and deployed.
Although WAIC 2026 has concluded, the exploration of world models entering industry continues.
Looking ahead, Shengshu Technology will continue advancing the development and application of general world models, driving model capabilities deeper into digital content, real-time interaction, embodied intelligence, and more real-world scenarios, further unleashing human creativity and productivity.