Shengshu Technology Releases Vidu S1, Ushering Video Generation into the Era of Real-Time Interaction

On July 3, at the AI Integration and Application Forum of the 2026 Global Digital Economy Conference, Shengshu founder Zhu Jun delivered a keynote titled “General World Models: A New Paradigm for Unifying the Digital and Physical Worlds,” and officially released Vidu S1, a next-generation model designed for real-time interactive scenarios. During the conference, the Beijing Software and Information Services Association (BSIA) released the “2025 Beijing Digital Economy Benchmark Enterprise Evaluation Report,” and Shengshu Technology was recognized as a “New Model, New Application Benchmark Enterprise” for its outstanding innovation and industrial applications.
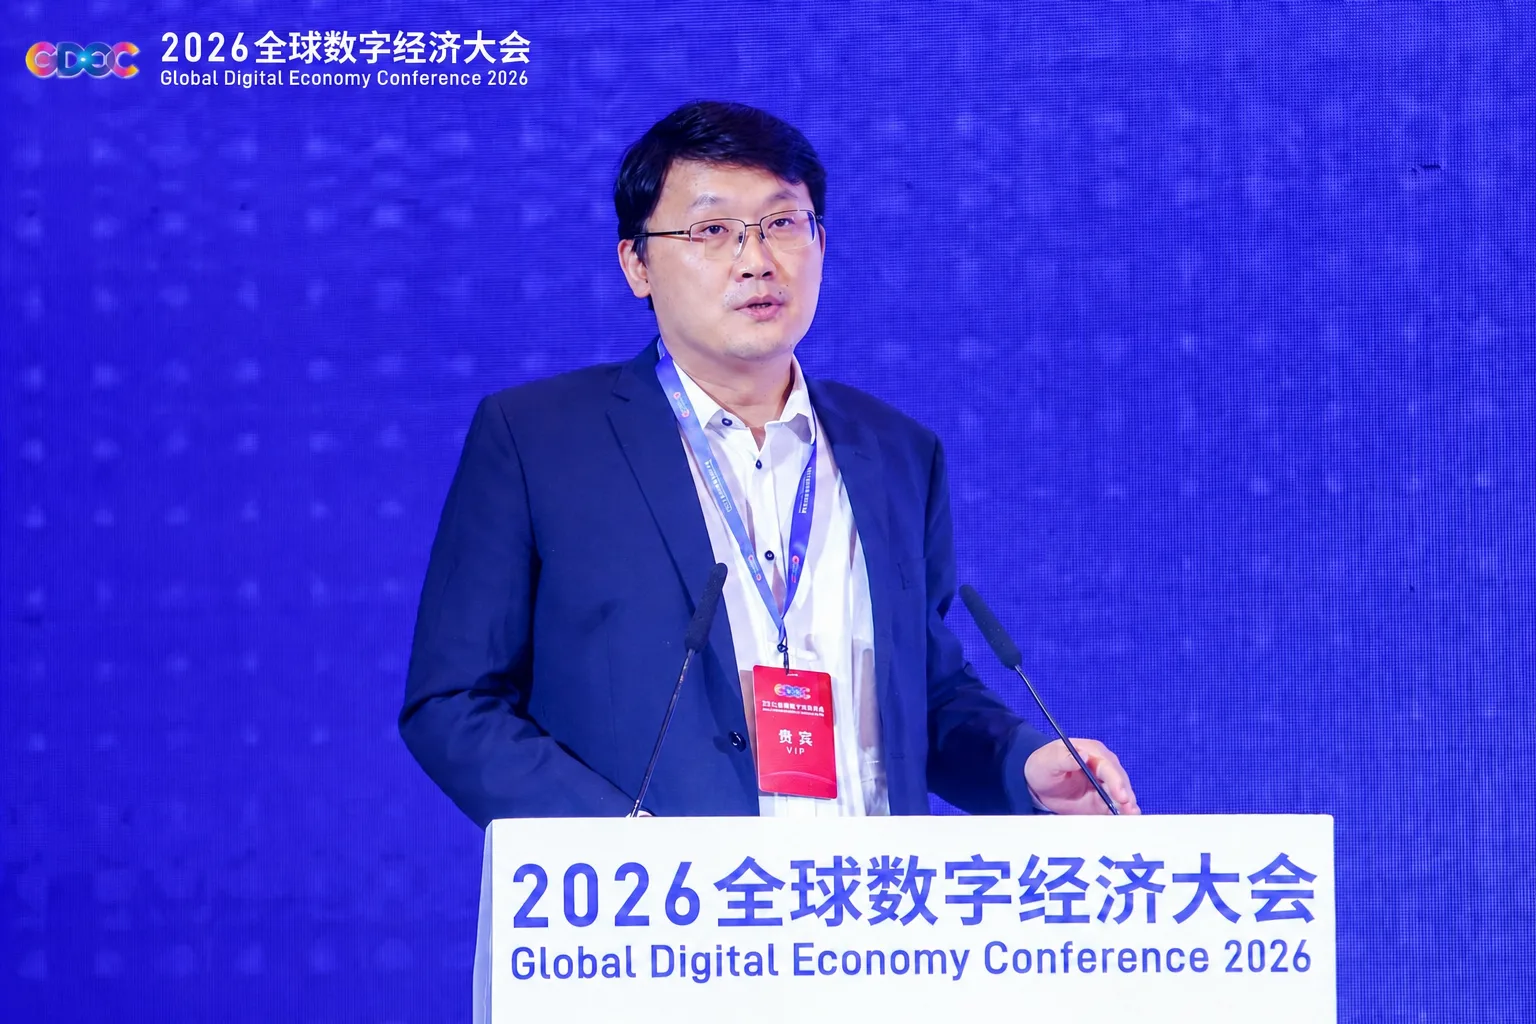
Global Digital Economy Conference keynote

The Vidu S1 Real-Time Interactive Model provides a new generation of real-time interactive video generation capabilities, pushing AI video from “generating a piece of content” toward “continuous interaction.”

The model supports real-time video calls and voice-controlled video generation. Users can not only control digital character behavior through voice but also achieve unlimited-duration continuous interaction. Vidu S1 supports 540P (960x540) high-definition resolution, 25FPS (up to 42FPS) frame rates, and can quickly create dedicated interactive characters based on any initial image — real people, anime characters, pets — with personalized voice, delivering a more natural, fluid, and immersive real-time interactive experience.
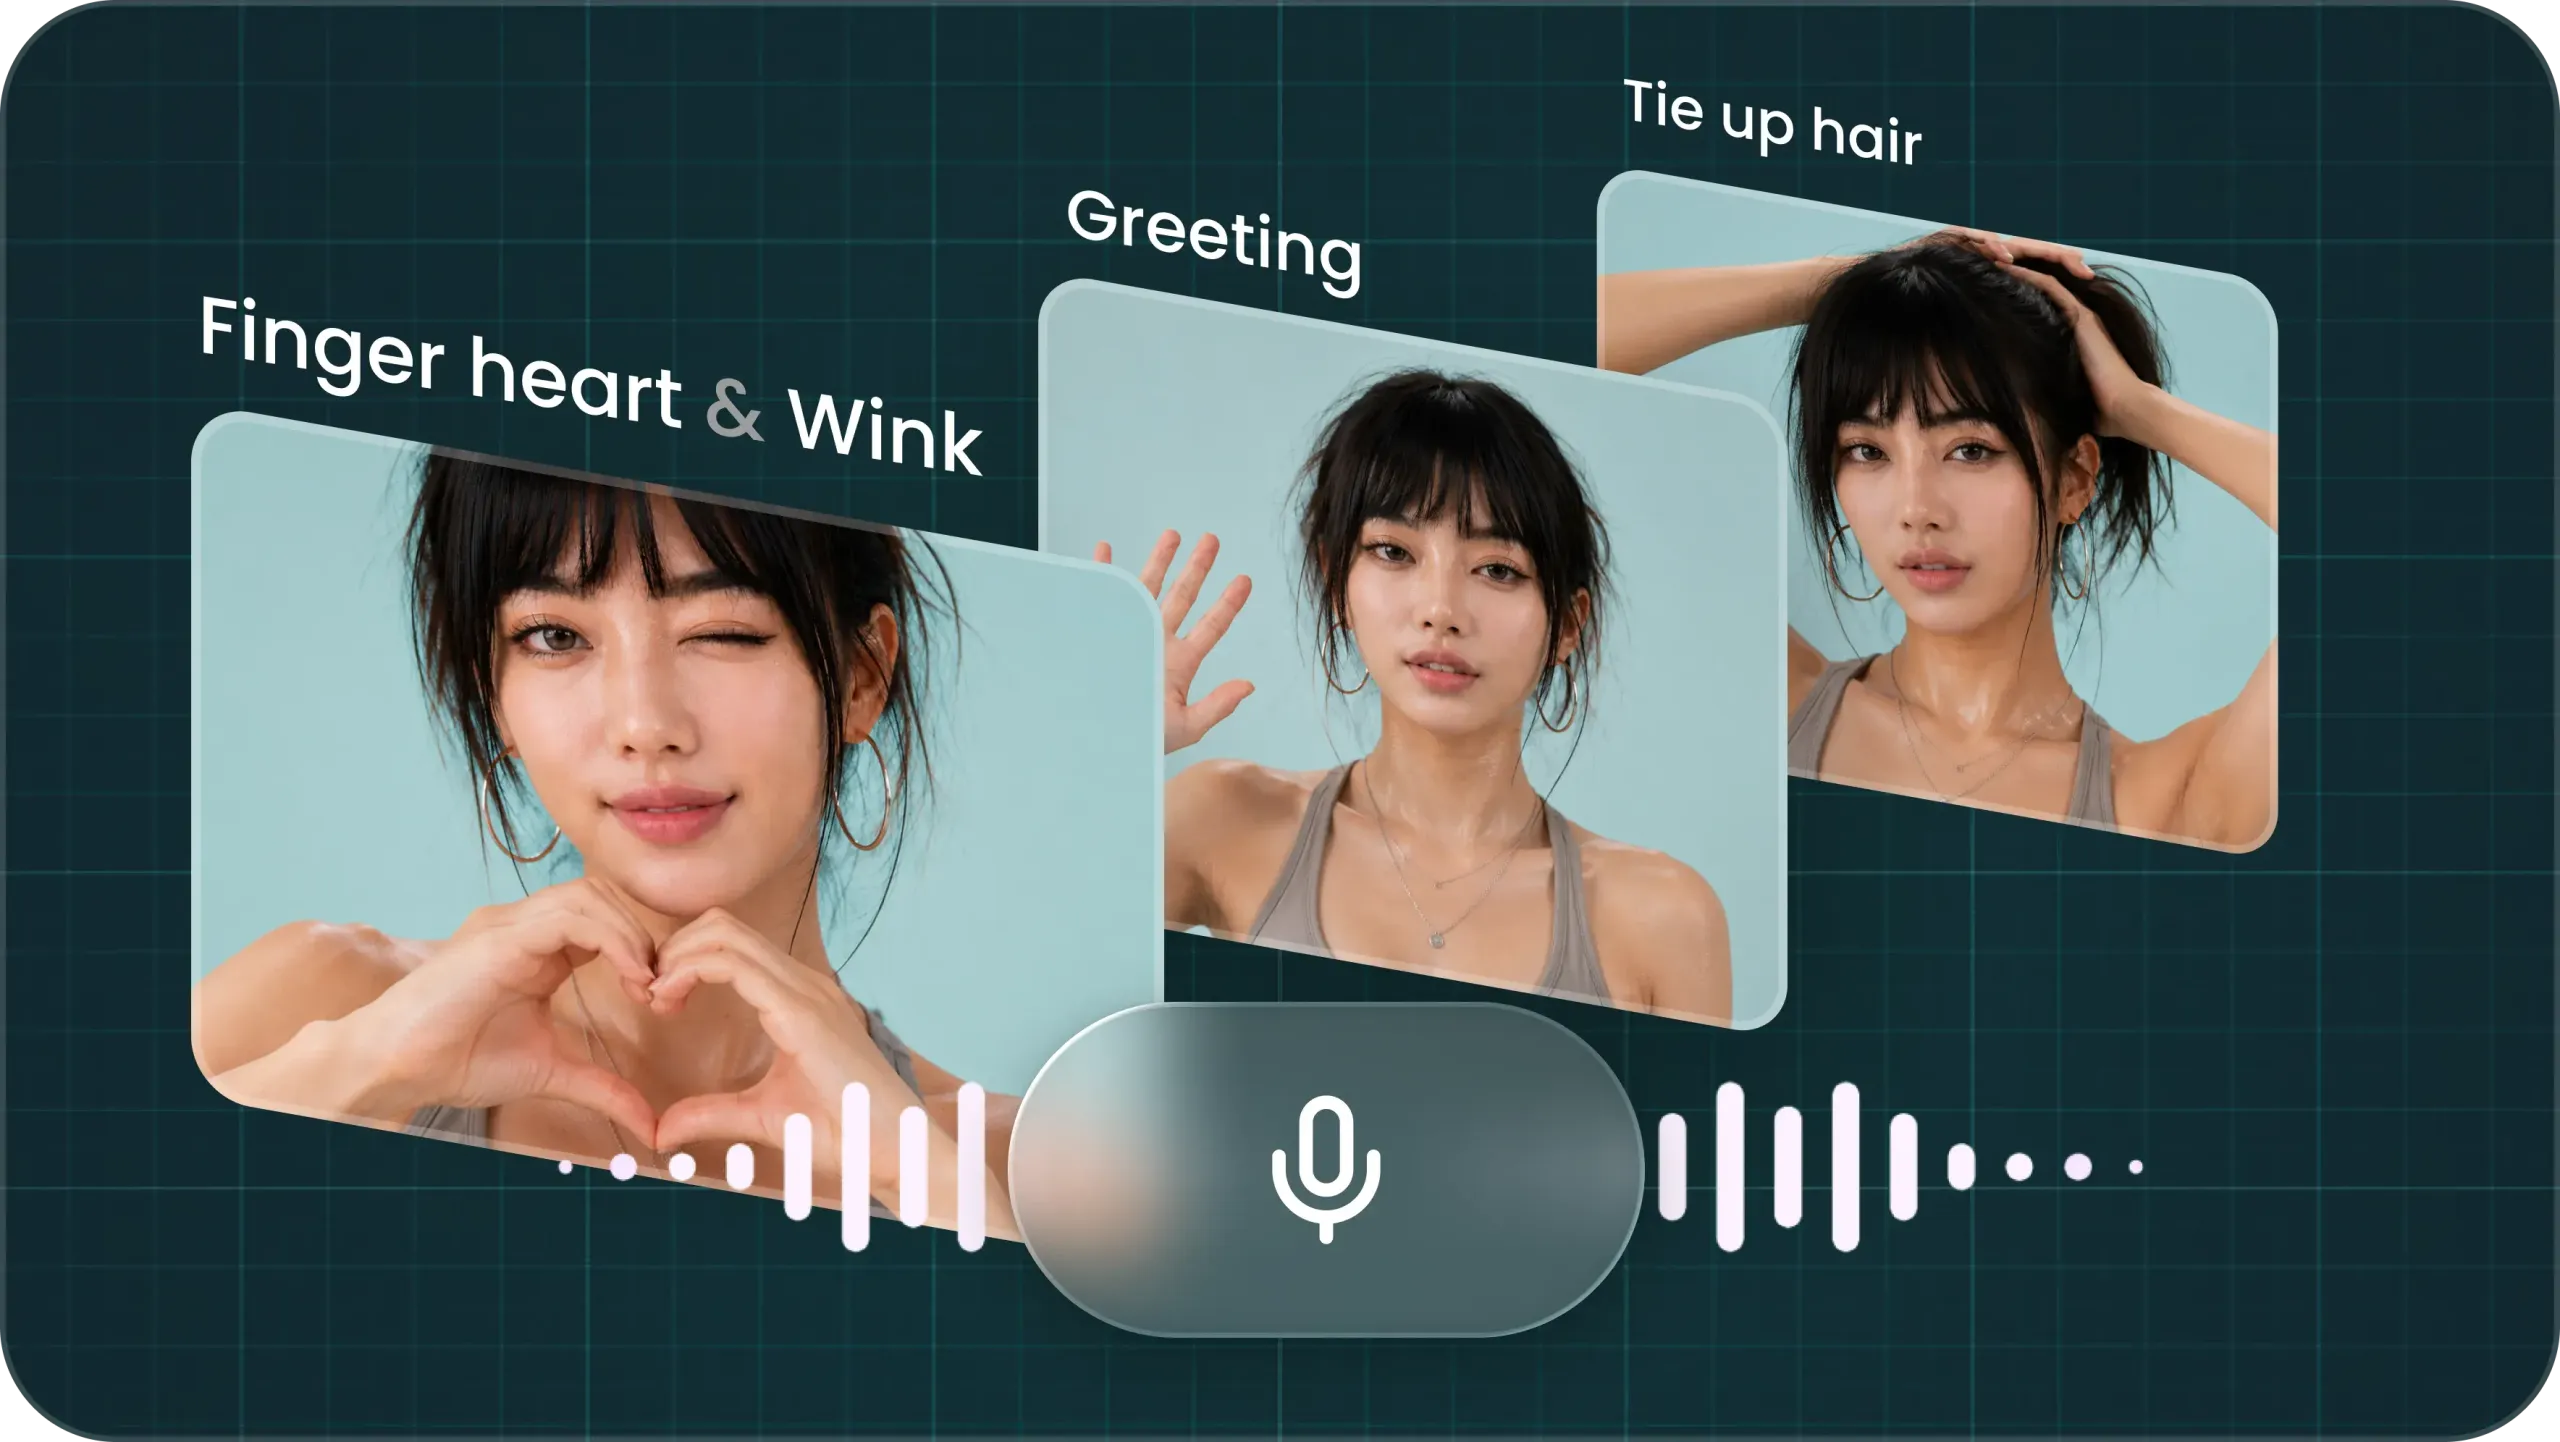
Real-Time Voice Command Following: From Offline Generation to Real-Time Response

Traditional large video models typically follow an offline mode: “input prompt — wait for generation — play result.” Once the video is generated, the content and direction are essentially fixed. To adjust actions or plot, users must re-enter prompts and regenerate. The relationship between humans and video remains offline — “generate and watch.”

Vidu S1 breaks this boundary. Users can continuously input voice during a video call, and the model combines voice content, dialogue context, and current visual state to generate the character’s subsequent content and actions in real time.

At the same time, Vidu S1 advances digital humans from “voice-driven lip-sync” toward “voice-controlled behavior.”

Unlike traditional digital humans that rely on “audio-driven lip-sync + preset action libraries,” Vidu S1 uses real-time video generation technology, upgrading voice from an audio signal driving mouth shapes to a real-time command controlling character visual behavior. The model generates not only lip-sync synchronized with speech, but also understands semantics, intent, and emotions, generating matching expressions, eye movements, gestures, body posture, and full-body actions in real time — evolving digital humans from “talking virtual avatars” into generative characters that understand users, respond instantly, and sustain interaction.

Voice control demonstration

Unlimited-Duration Real-Time Generation: Video That Continuously Evolves Through Interaction

Traditional video generation models typically generate a fixed 3s-30s clip at once. During generation, users cannot add new instructions to alter subsequent frames in real time.

Vidu S1 adopts an autoregressive diffusion model (AR + Diffusion) approach. Instead of generating a complete video at once, it builds on previously generated frames, combined with current voice commands and dialogue context, to continuously predict and generate subsequent content. When users issue new voice commands, the model can understand and adjust the character’s expressions, actions, and video direction in real time, transforming video from predetermined fixed content into a continuously generated, real-time responsive, dynamically evolving interactive process.

AR+Diffusion architecture

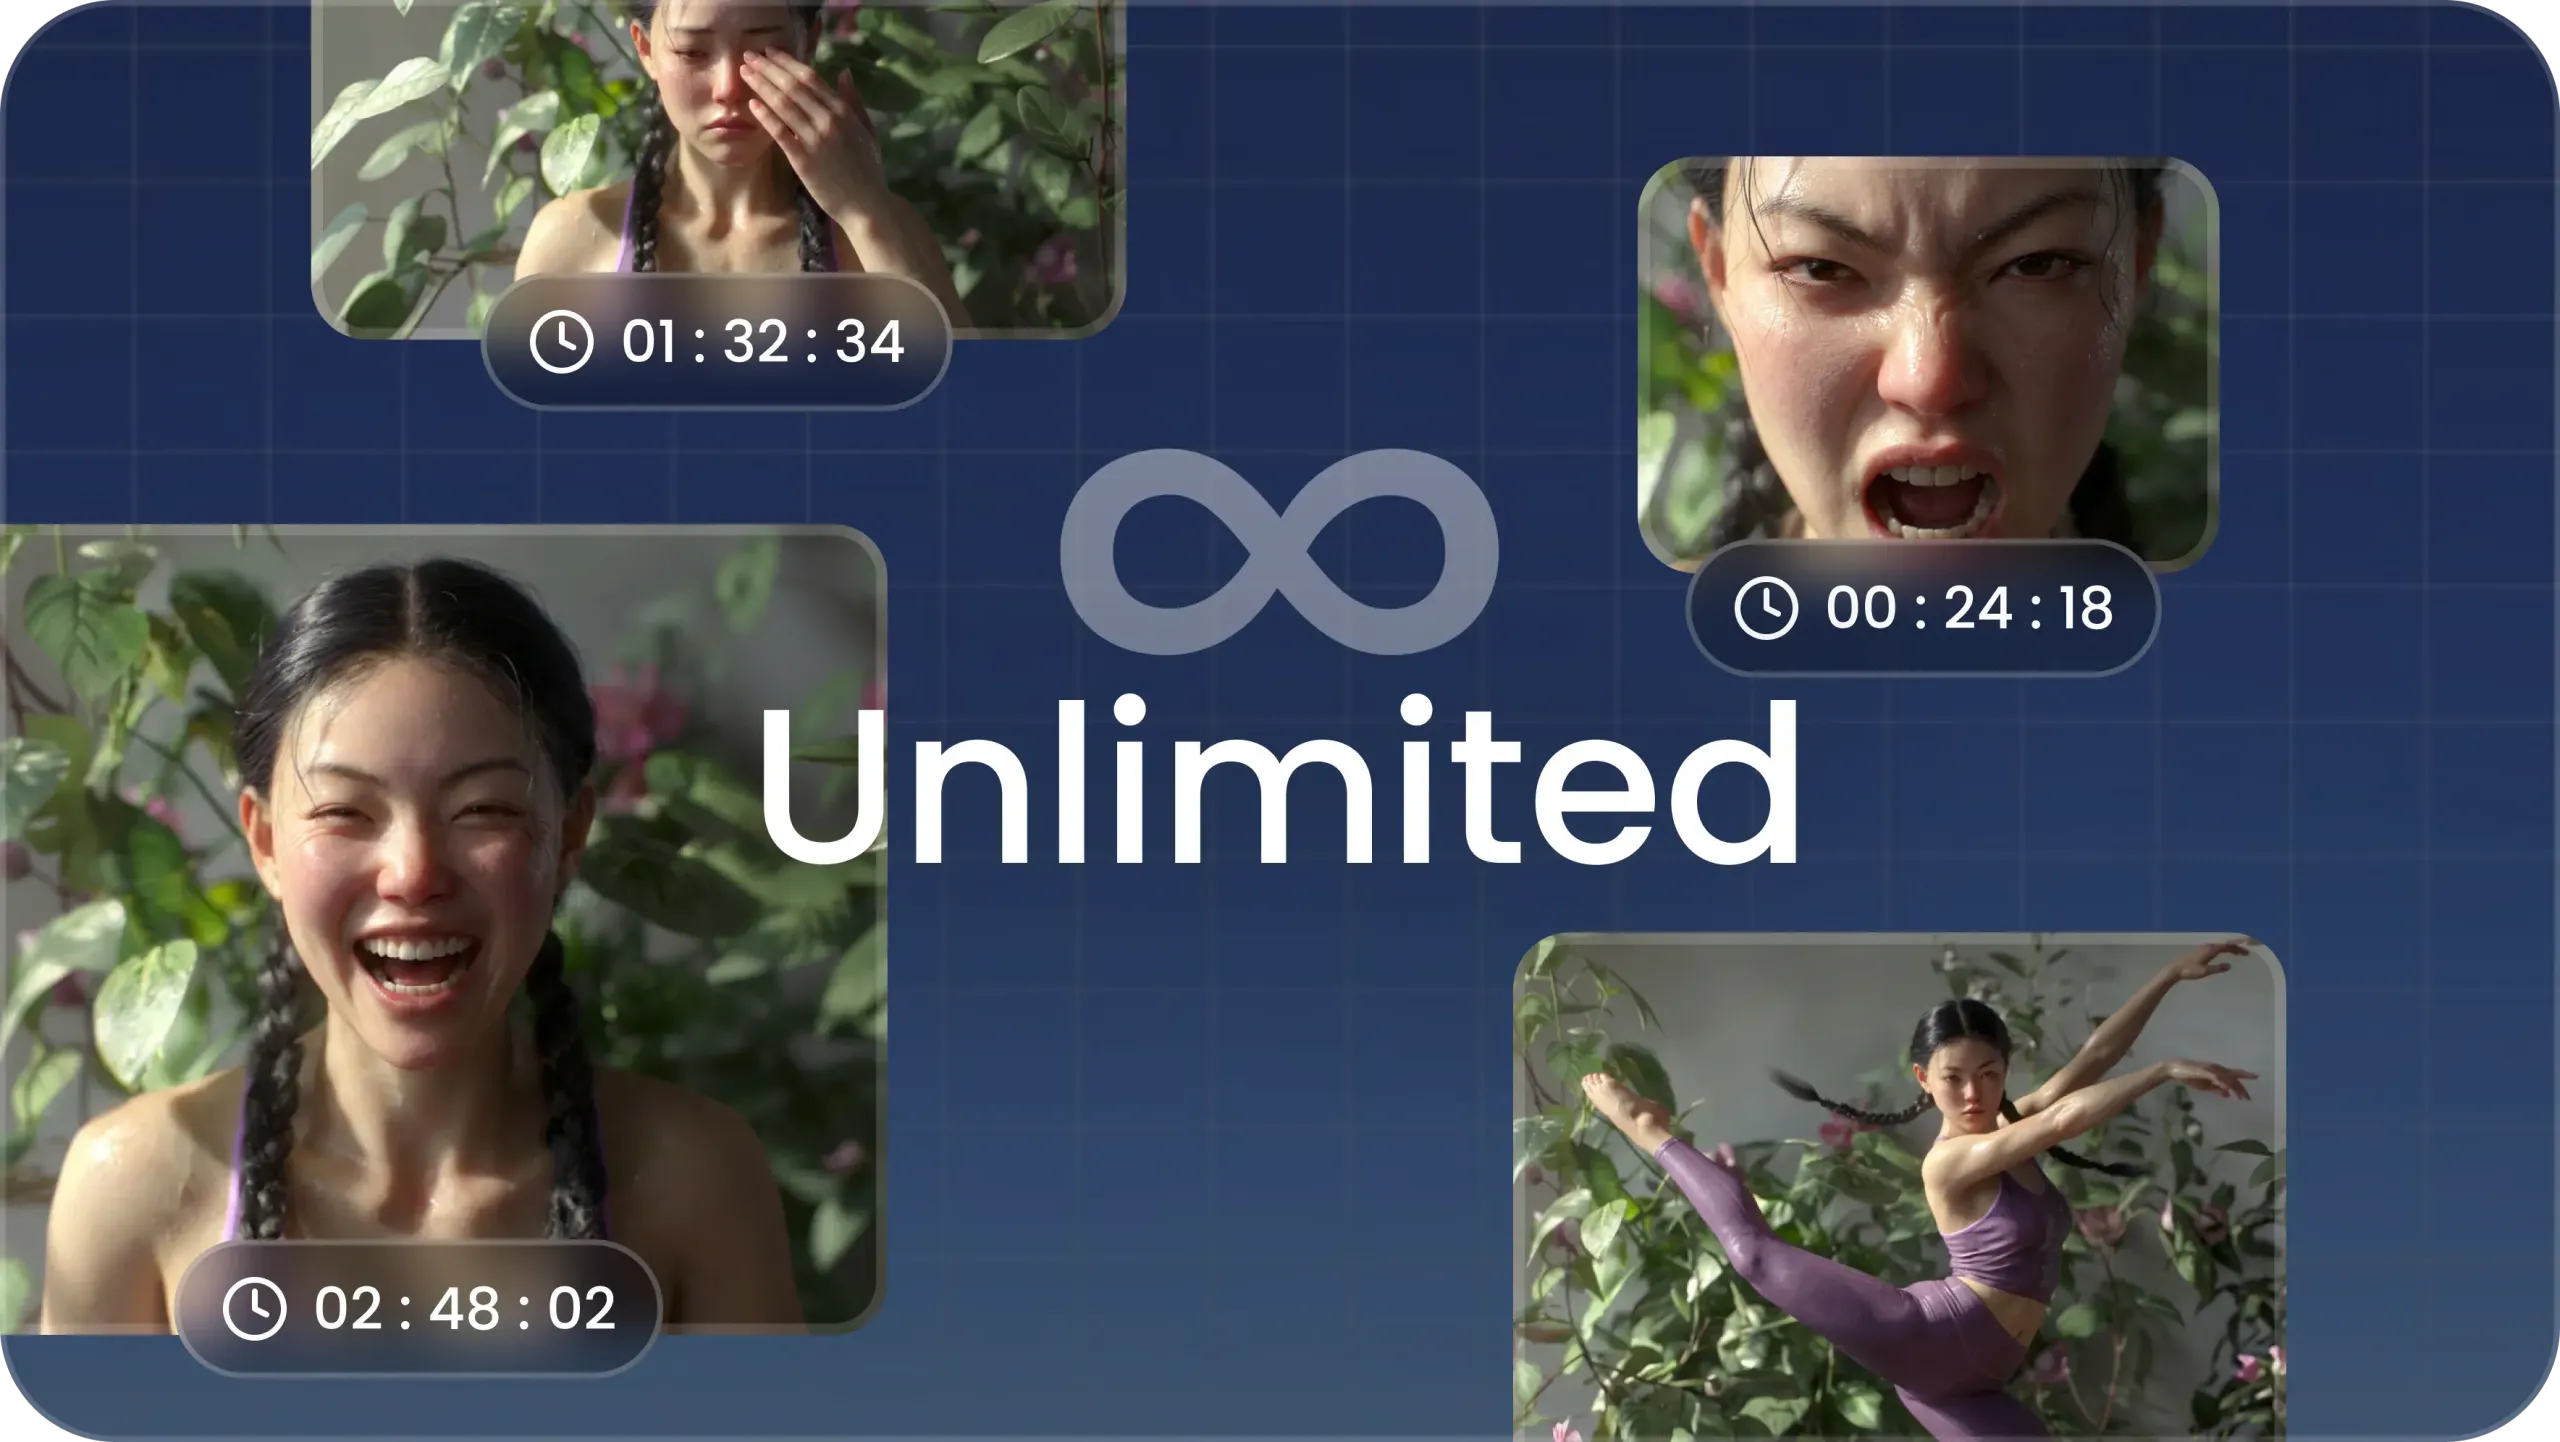
Beyond interactive real-time generation, Vidu S1 also achieves unlimited-duration real-time video generation for the first time. Even with continuous generation lasting hours, the visuals remain stable without rapid drift or degradation.

Achieving long-duration continuous interaction requires more than just “continuous generation.” The model must also maintain stable character identity and natural, coherent motion throughout extended operation, while continuously receiving user commands and responding in real time. Vidu S1 maintains stable character appearance and natural motion coherence during long-duration generation, while continuously receiving user voice commands and responding in real time — the first to achieve unlimited-duration generative video interaction.

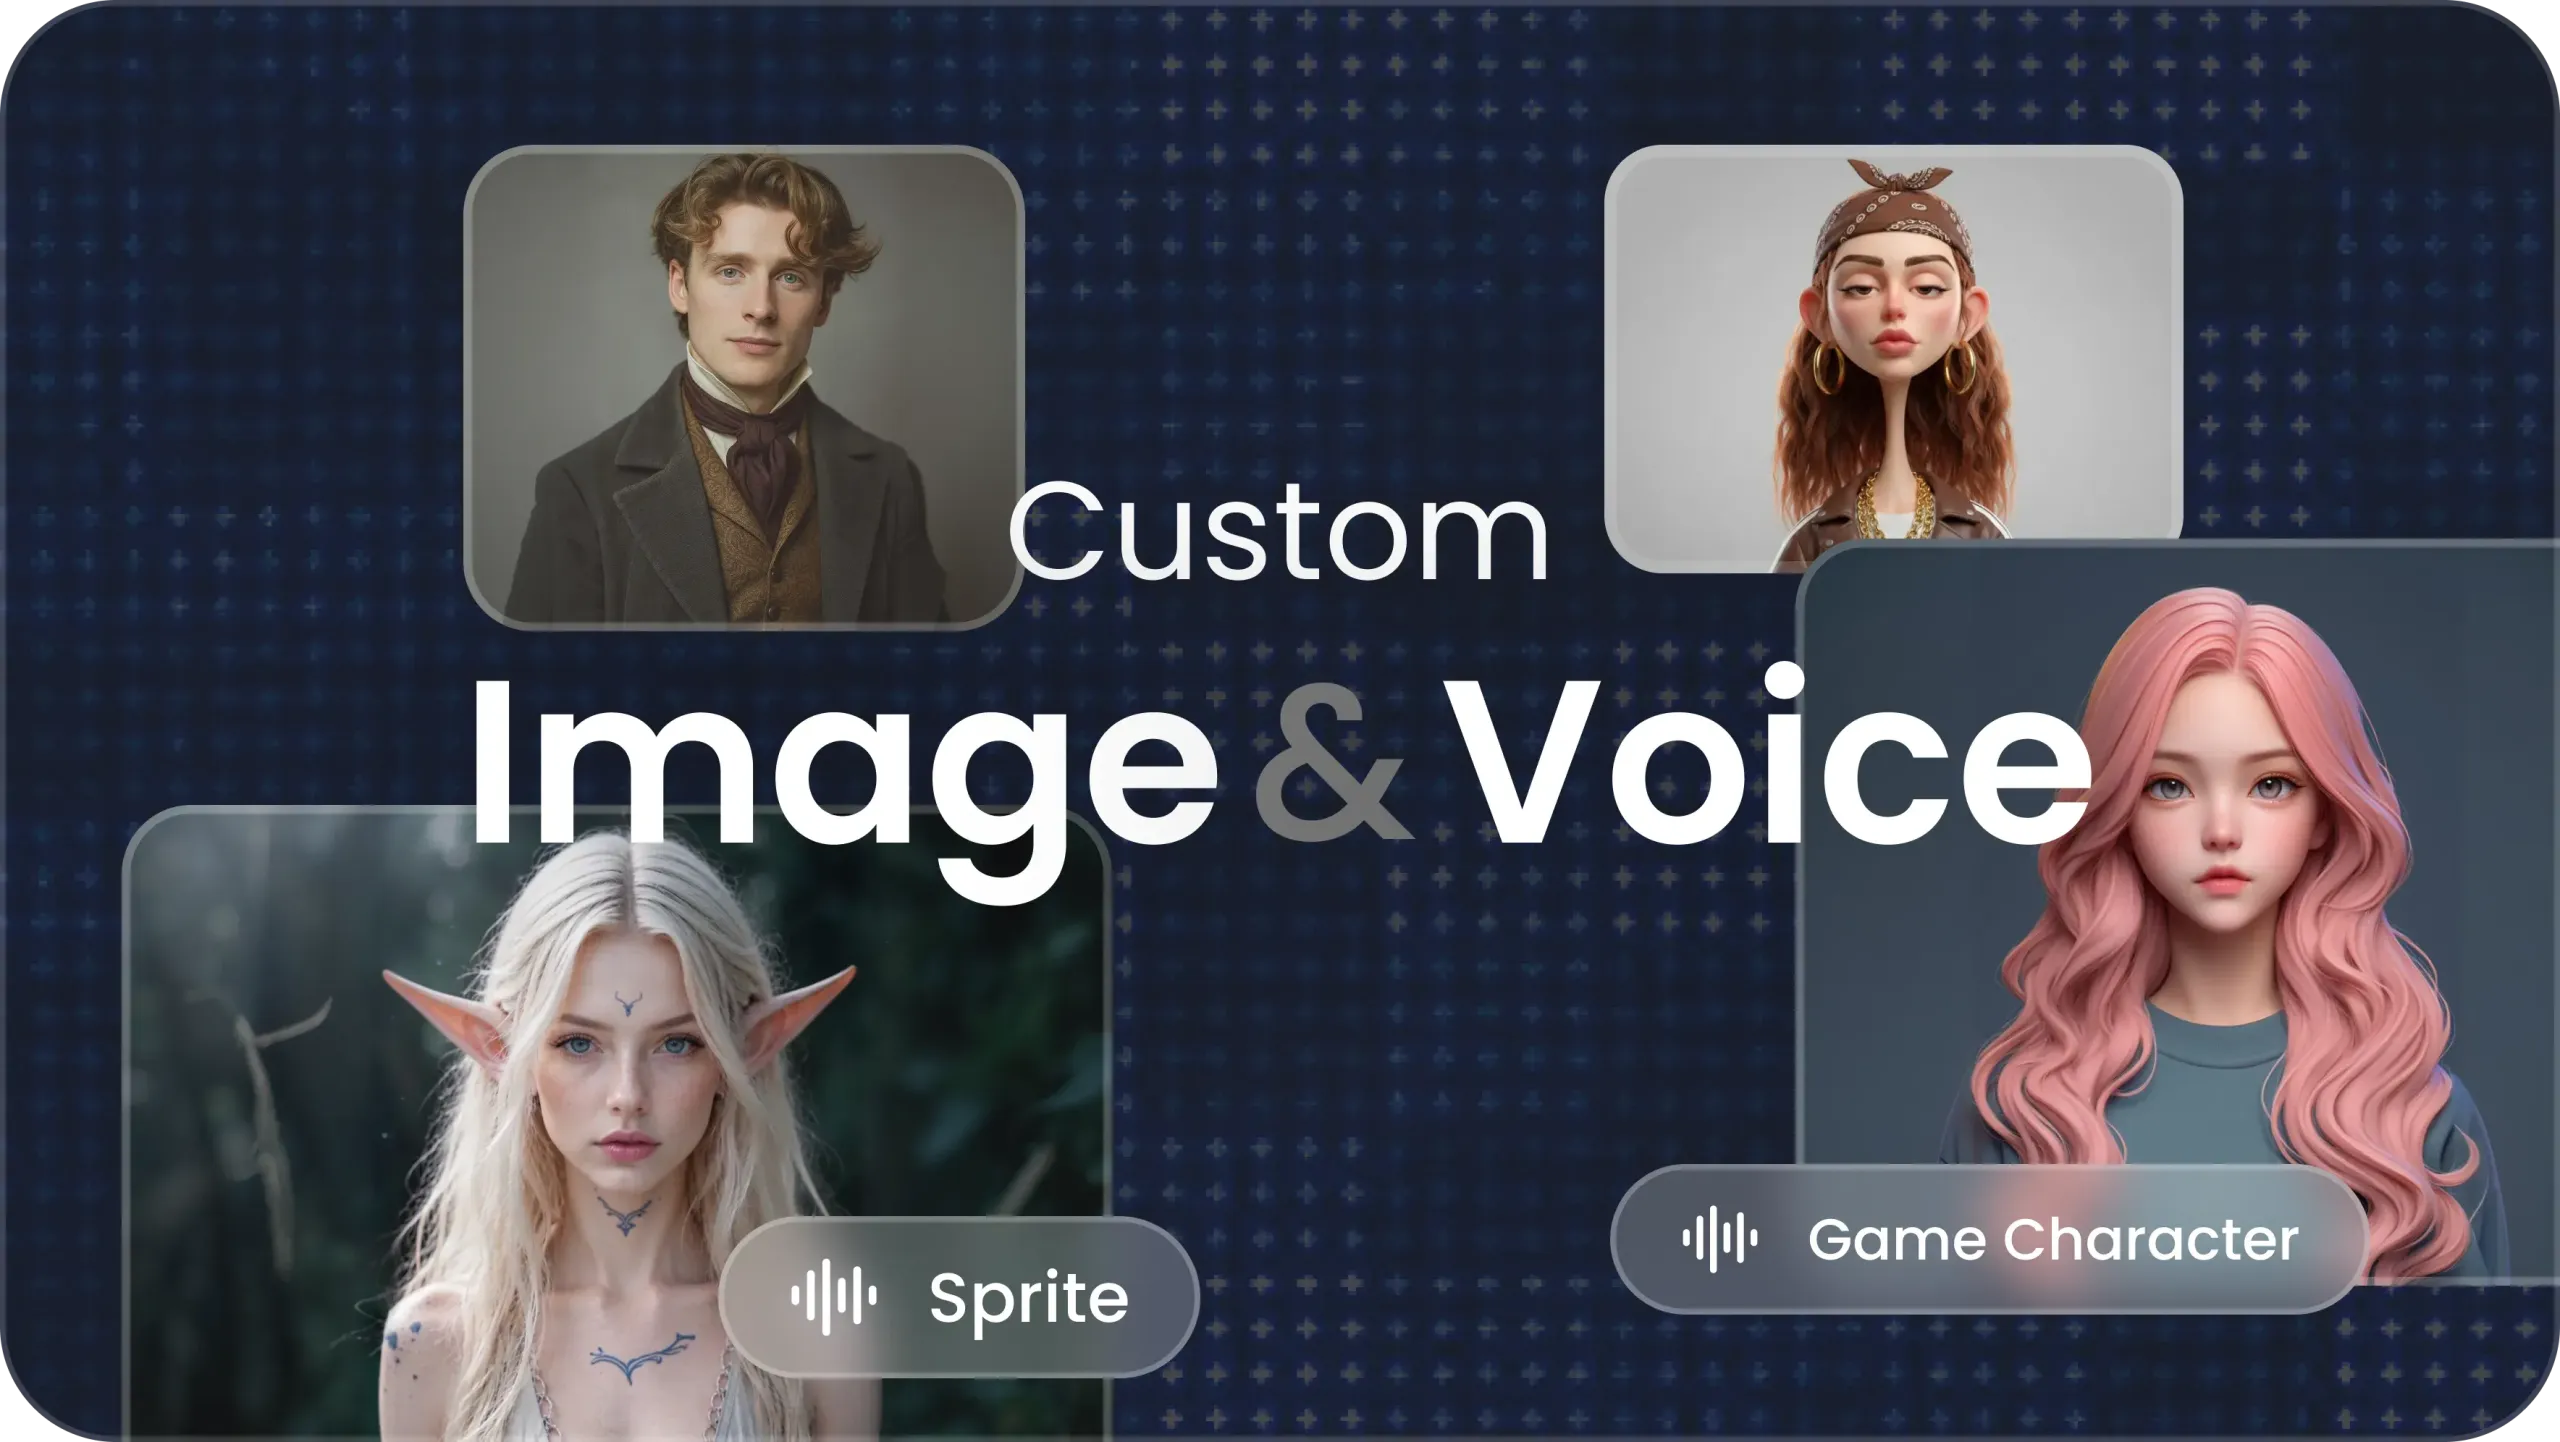
Custom Characters: No Modeling or Training Required — One Image to Create a Real-Time Interactive Character

Creating traditional digital humans typically requires uploading multiple images or video materials, followed by modeling, character rigging, lip-sync adaptation, and individual training — a lengthy production process.

Vidu S1 adopts a purely generative technical approach, requiring no offline modeling or training for each character. Users simply upload a single initial image, and the model understands the character’s identity, appearance, and visual style, generating lip-sync, expressions, actions, and body posture in real time.

Whether it’s a real person, anime character, or pet, any image can be quickly transformed into a real-time interactive generative character. Vidu S1 also supports custom voice, achieving unity of visual appearance and voice identity.

The character creation method shifts from “upload materials and wait for training” to “upload an image and interact immediately” — dramatically lowering the barrier for creating personalized real-time characters.

Custom character creation

540P 25FPS Real-Time Interaction: Video Call-Grade Experience

Real-time interaction requires not only streaming generation, but also resolution and frame rate quality under real-time constraints.

Vidu S1 is optimized for real-time interactive scenarios through coordinated optimization of model acceleration, inference engines, and cluster deployment strategies, achieving 540P (960x540) high-definition resolution, 25FPS (up to 42FPS) smooth frame rate real-time video generation.

540P real-time generation

On the model side, Vidu S1 leverages Shengshu’s TurboDiffusion inference acceleration framework, along with few-step generation, low-bit attention (SageAttention), sparse attention (SLA), and SpargeAttention inference optimization techniques, significantly reducing per-frame computation costs. 540P resolution at 25FPS (up to 42FPS) real-time generation is achievable on consumer-grade GPUs.

On the system side, Vidu S1 uses Shengshu’s TurboServe inference deployment engine for efficient inference request scheduling. The system continuously tracks user input, character state, and historical frames, dynamically allocating computing resources based on interaction state.

Through coordinated optimization of model inference and streaming services, Vidu S1 achieves the critical leap from “generating video faster” to “keeping video continuously online, stably outputting, and responding in real time.”

540P and 25FPS (up to 42FPS) are not just image quality and frame rate metrics — they mark the point where real-time video generation begins to have the technical foundation to enter video calls, interactive live-streaming, real-time companionship, interactive gaming, and XR scenarios.

As large video models continue to develop, industry competition is shifting from single-point capabilities like image quality, duration, and speed toward a systemic competition of real-time performance, controllability, and interactivity.

The release of Vidu S1 transforms video from pre-generated, offline-viewed fixed content into an interactive medium that can understand instructions, respond in real time, and continuously evolve.

In the future, Vidu S1 can be widely applied in AI emotional companionship, AI virtual idols, interactive live-streaming, game NPCs, brand digital humans, intelligent customer service, online education, and XR scenarios,推动 digital characters from one-time content assets into long-term online, continuously interactive intelligent entry points.

From generating a video to creating a character that can sustain interaction; from offline content output to real-time two-way communication — Vidu S1 further extends the capability boundary of large video models, pushing AI video generation into a new era of real-time interaction.

Vidu S1 is fully open. Users can customize initial images for real-time interactive experience, and the API platform is also available: